01 / 06
.
AI-assisted idea triage for an innovation challenge, built for INSKIP
- Category
- AI Product · Full-Stack
- Role
- Solo, end to end
- Link
- Open the app
By the numbers
- 40
- real ideas triaged end to end
- 80
- unit tests + Playwright e2e
- 5/5
- duplicate pairs caught
Overview
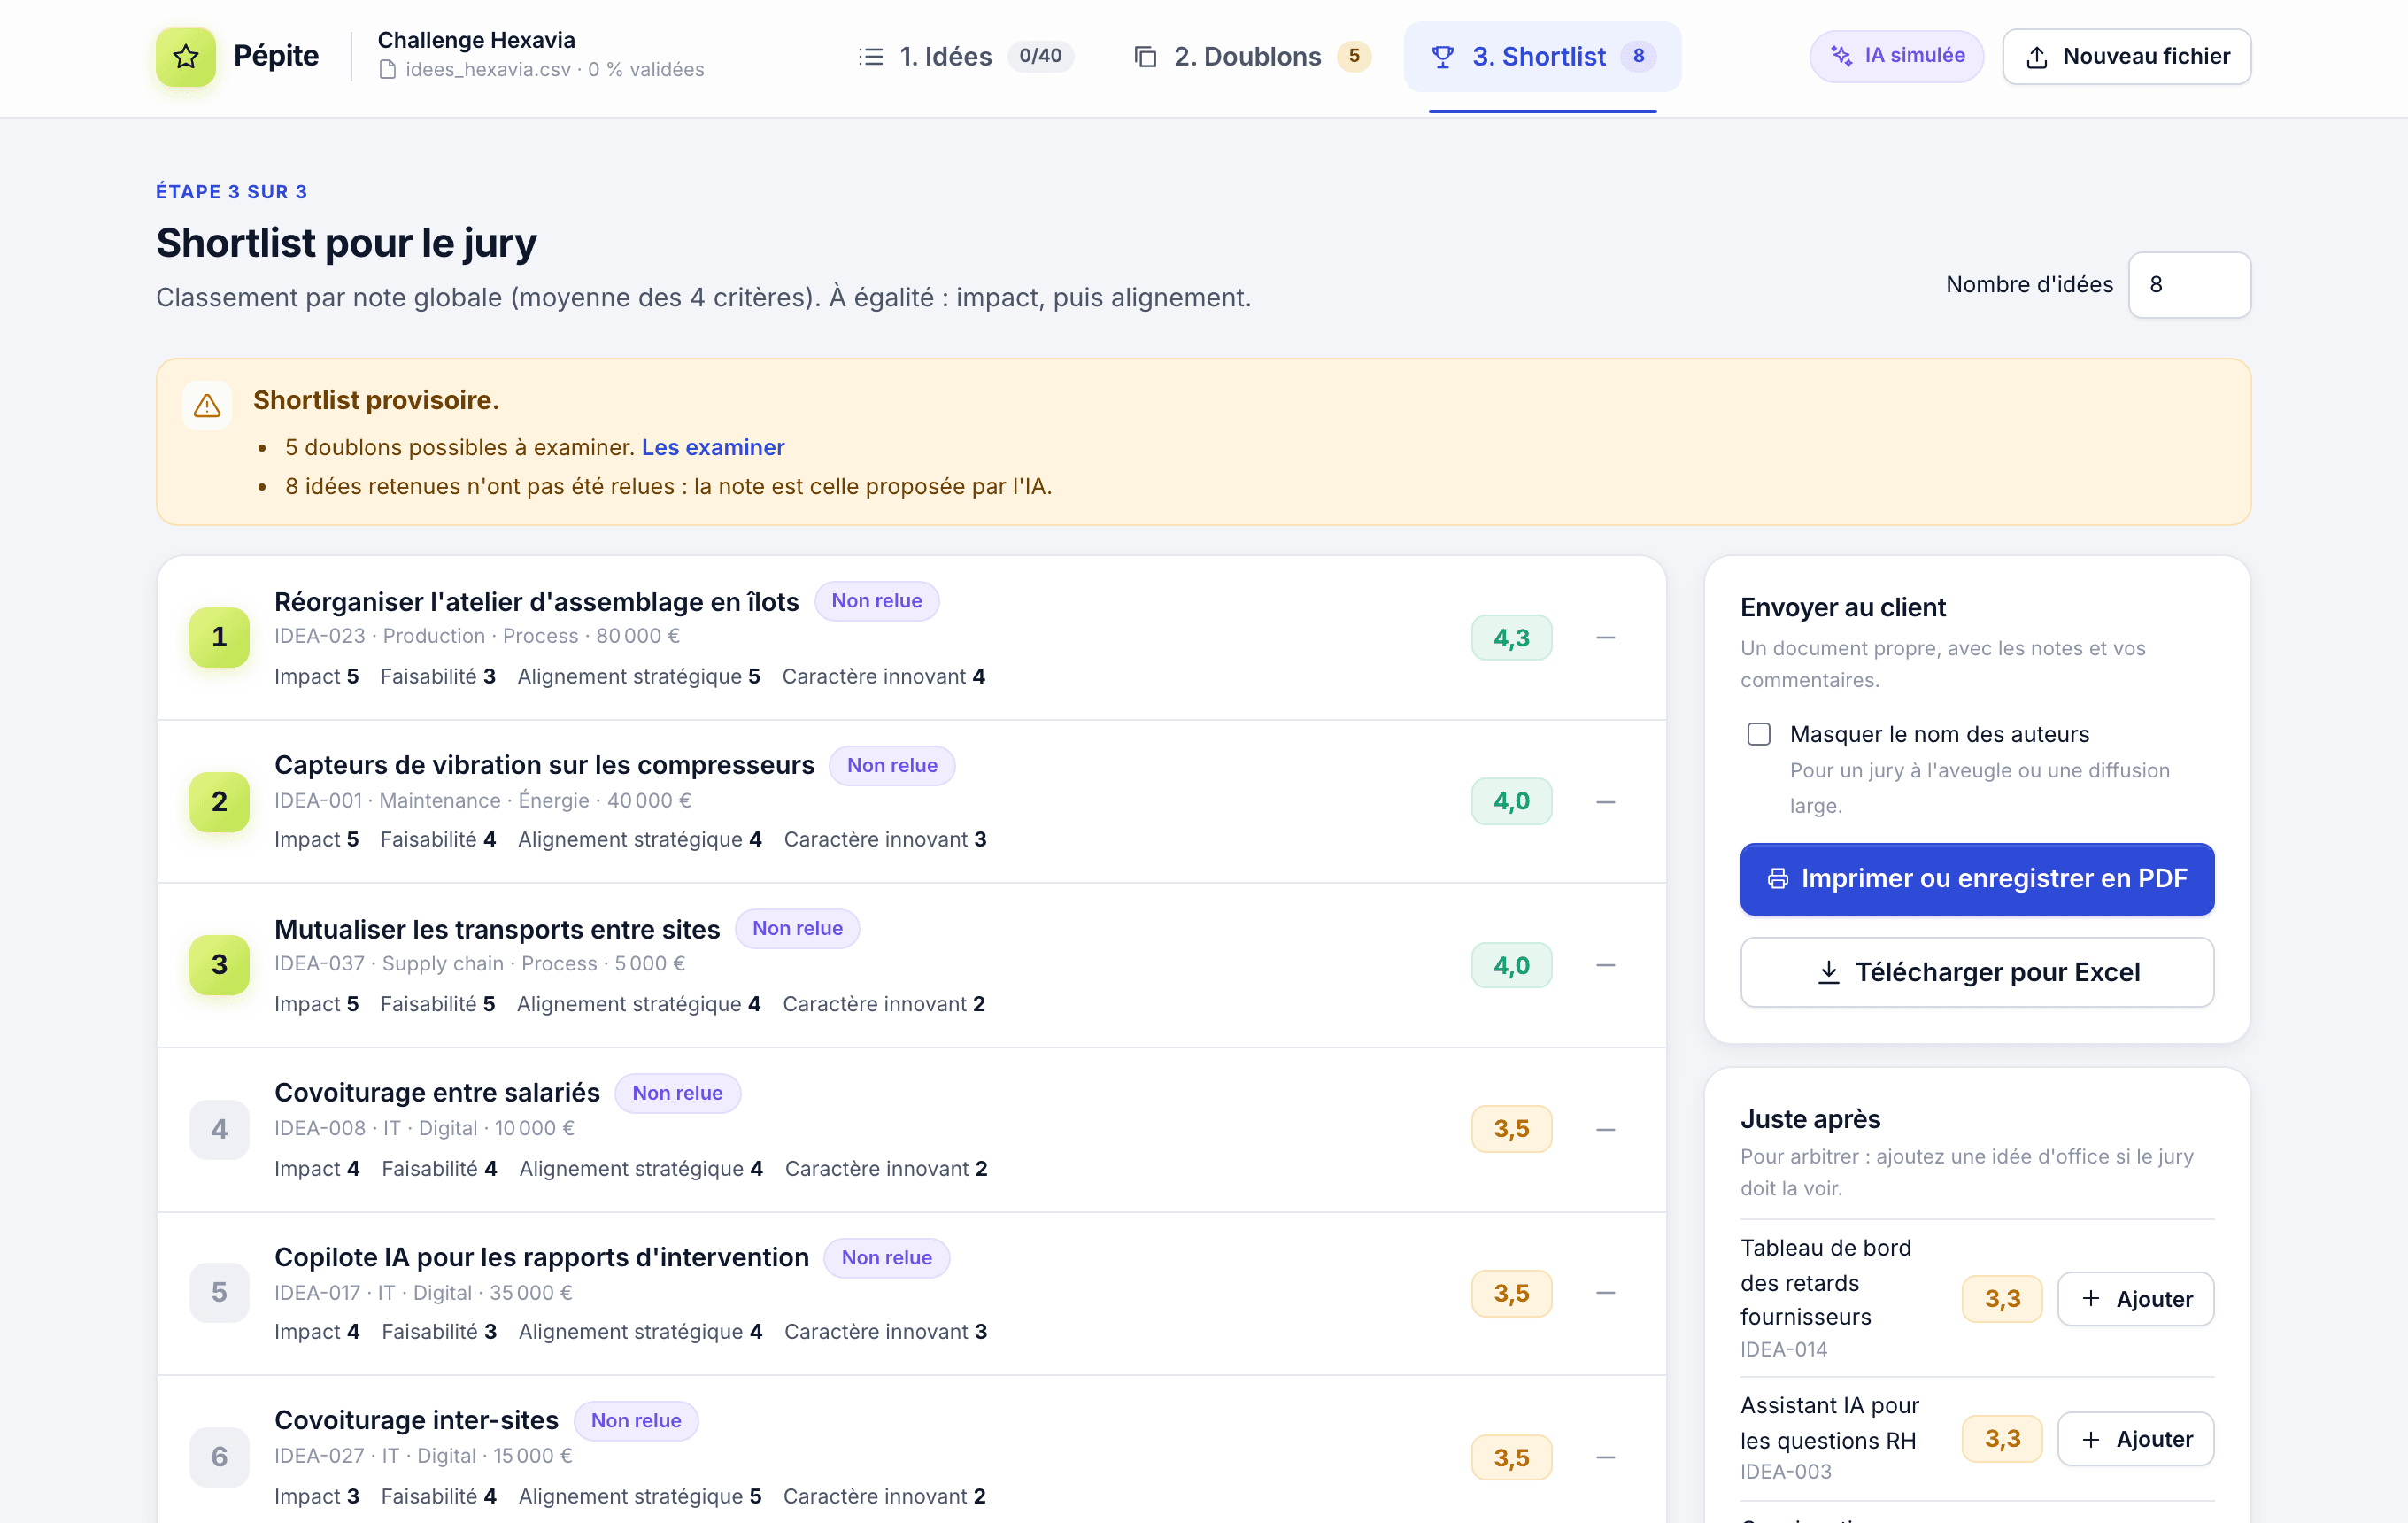
Built for INSKIP: their consultant had ten days to bring about 8 of 40 ideas to a jury, and scoring them in Excel was slow and inconsistent. Pépite gives her one place to read and filter ideas, a justified first score on the client’s grid that she can correct in one click, duplicate detection and a presentable shortlist exported to PDF and Excel. It is a React + TypeScript + Vite app with no database: everything stays in her browser, and a single server function holds the model key so employee names are never sent to the AI.
When real data broke the AI
Tests passed on sample data, but the real export exposed wrong scores: “Programme ambassadeurs clients” scored high on strategy because the keyword “eau” (water) matched inside “nouveaux”. I switched to word-start matching with a regression test, and added a synonym table after two duplicate pairs (“chatbot” and “assistant conversationnel”) were missed. In production, the scoring function returned 500 on Vercel while passing locally; I caught it by querying the live URL after deploy and fixed the extensionless imports Node rejected.
Highlights
- 01Robust CSV import: BOM, separators, multi-line fields, 7 date formats and 15 budget formats, with every issue flagged instead of dropped.
- 02AI proposes, the consultant decides: AI scores and her scores are stored separately, and hers always win.
- 03Explainable duplicate detection with TF-IDF similarity, shared words highlighted, threshold tuned on real data (0.30).
- 04Simulated AI returns the exact schema of the real model, so switching to Claude changes nothing else.
- 05A test proves no first or last name ever reaches the model prompt; the API key lives server-side only.
- 06CI on every push: secret and CSV leak checks, lint, build, unit and end-to-end tests.
What’s next
Next up: the real Claude model behind authentication, multi-reviewer scoring with Supabase, and a PowerPoint export for the jury.